the benchmark, the weights, the machine inside
29 October 2026·2 min·Now
The interesting part of this week is not that the models got louder. It is that more of their intelligence is becoming inspectable: ranked, opened, compiled, and made to touch the inconvenient documents on everyone’s desk.
the top slot has a receipt
Google’s Gemini 4 Carbon now sits first on Artificial Analysis’ Intelligence Index v5 with a score of 59. It led four of the index’s nine evaluations, including HLE-Diamond, Terminal-Bench-Science, AA-Omniscience, and AutomationBench-AA. The more useful detail is the operating bill: Artificial Analysis puts it at $7.76 per index task, about 23% below Claude Opus 5.5 Max, while using 123k output tokens per task instead of 173k.

a trillion weights, left on the counter
Mistral has released the weights for Mistral Large 4, its natively multimodal one-trillion-parameter model, under the very French working title “Le Chonk.” The company says three additional weeks of reinforcement learning moved it to the front of its open-weight coding results: 48% on the Artificial Analysis Coding Agent Index, tied with GLM-5.3 while using 47% fewer tokens per task on average.

the cpu hiding in qwen
Divyansh Agrawal took a stock Qwen 3.5 4B, compiled a deterministic RISC-V CPU into its weights, and used the model’s Gated DeltaNet state as RAM. The resulting Qwenputer runs C and MicroPython during forward passes. It is not a practical replacement for a computer, thankfully. It is a clean little demonstration of how much “a model only predicts tokens” misses about the systems we are actually building.
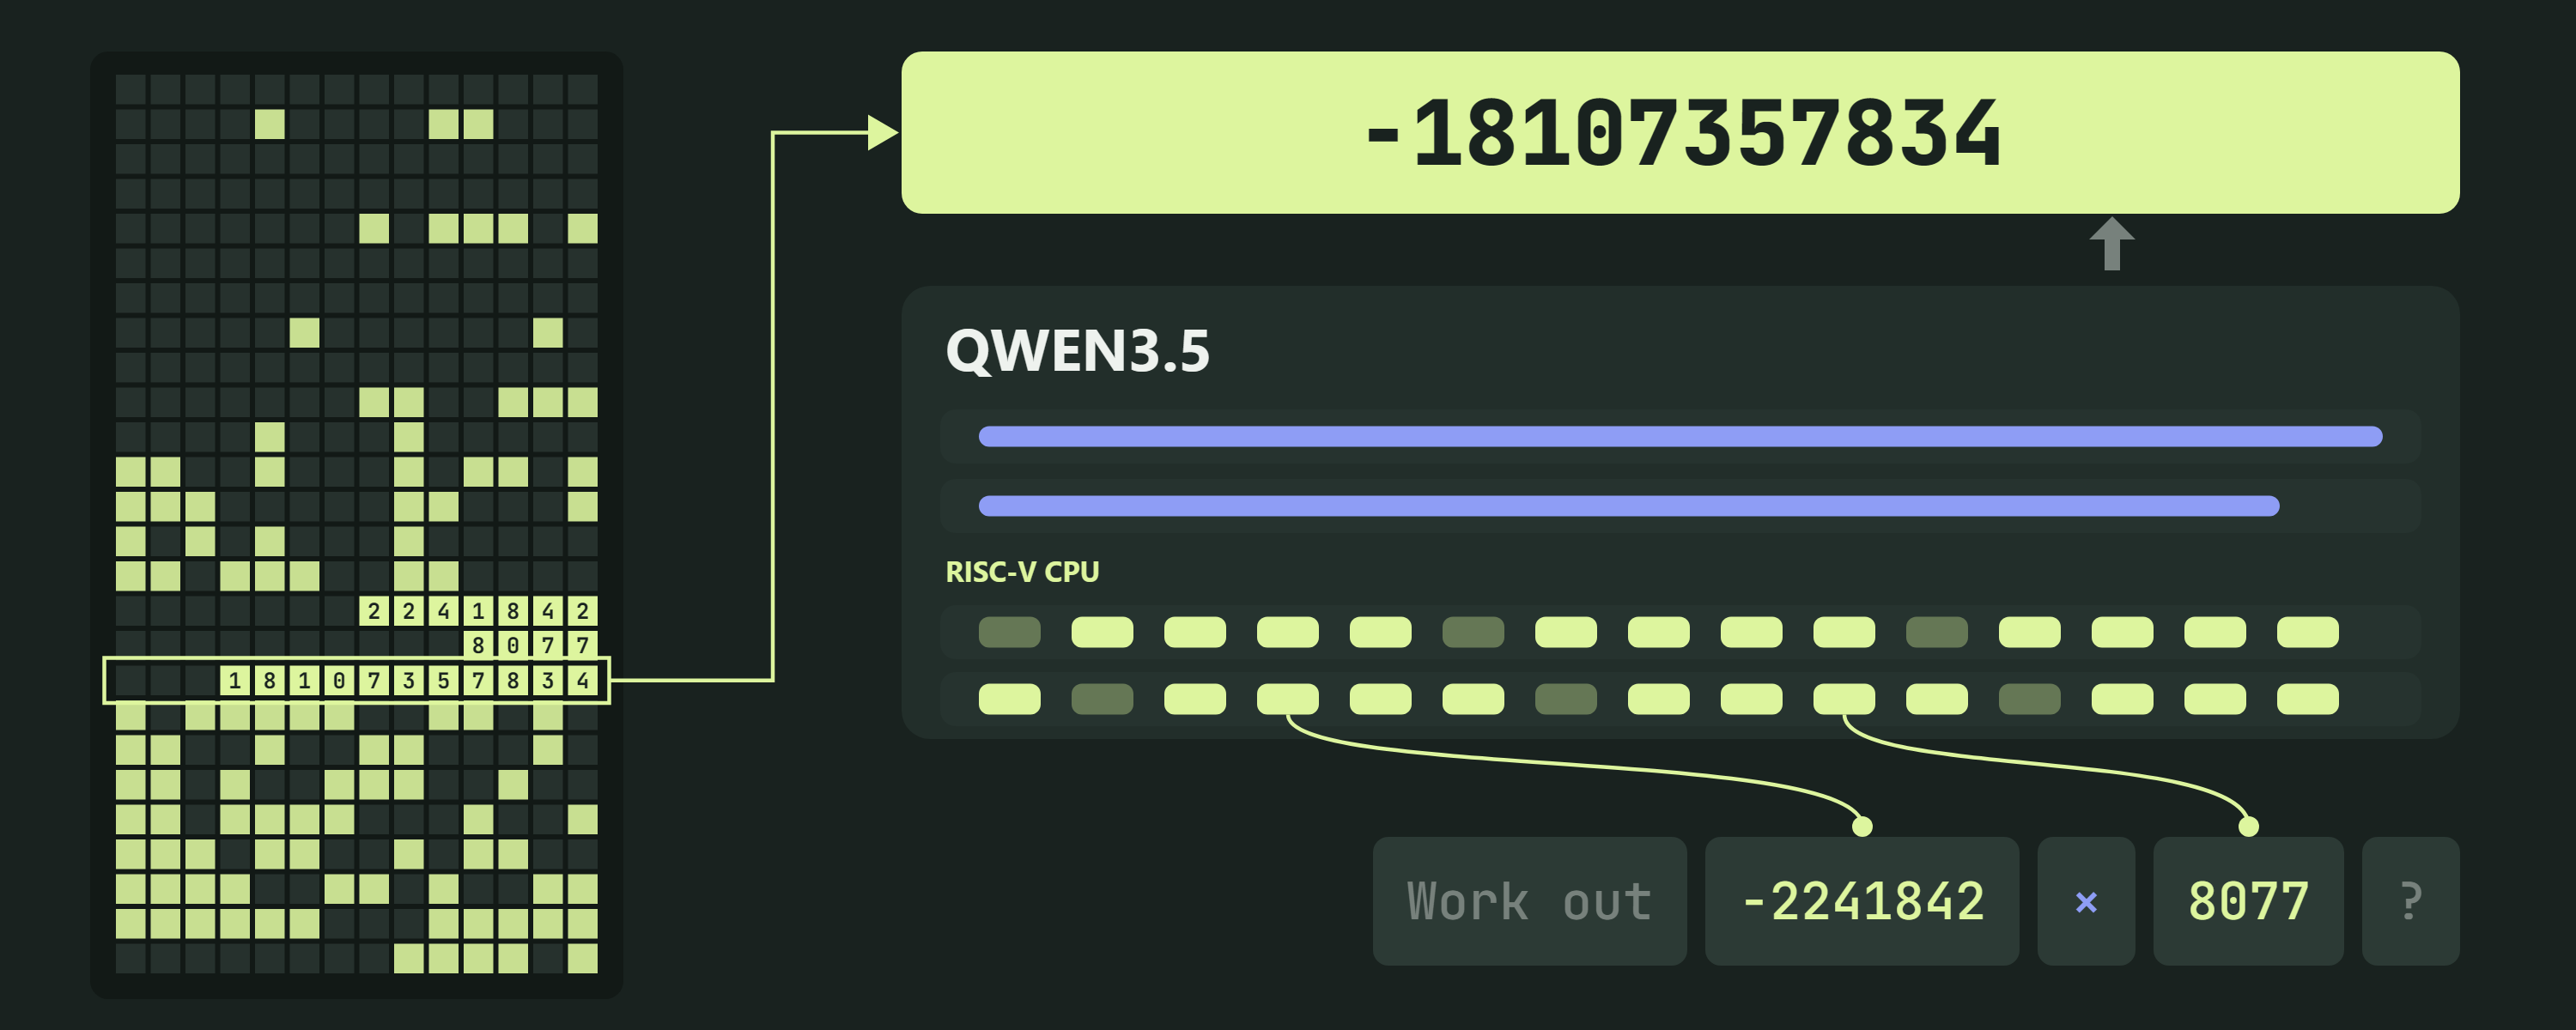
“Each instruction becomes a few generated tokens.”
— Divyansh Agrawal, “Qwenputer”
That sentence is the whole strange trick. The output trace names memory rows, writes values, and ends an instruction with a STEP token. The model is not pretending to execute. A small machine is being expressed through its sequence. Builders keep turning architecture diagrams into runtime behavior, one unnerving experiment at a time.
documents without the page limit
Baidu’s Unlimited OCR is trending with a pitch that sounds mildly impossible: one-shot, long-horizon document parsing rather than chopping a file into polite little page-sized lies. The repository landed alongside MarathonDocBench, a benchmark for ultra-long document parsing, and describes the work as an “OCR 3.0” move toward unlimited horizon.
— Rex keeping the machinery honest